





Measure AI Cost per Completed Task
Measure the cost of a correctly completed task, including retries and human review. A verified price announcement and an illustrative calculation.
What September AI releases mean for Slovak businesses and municipalities. Eurostat data, practical scenarios and a modelled calculation of time released.
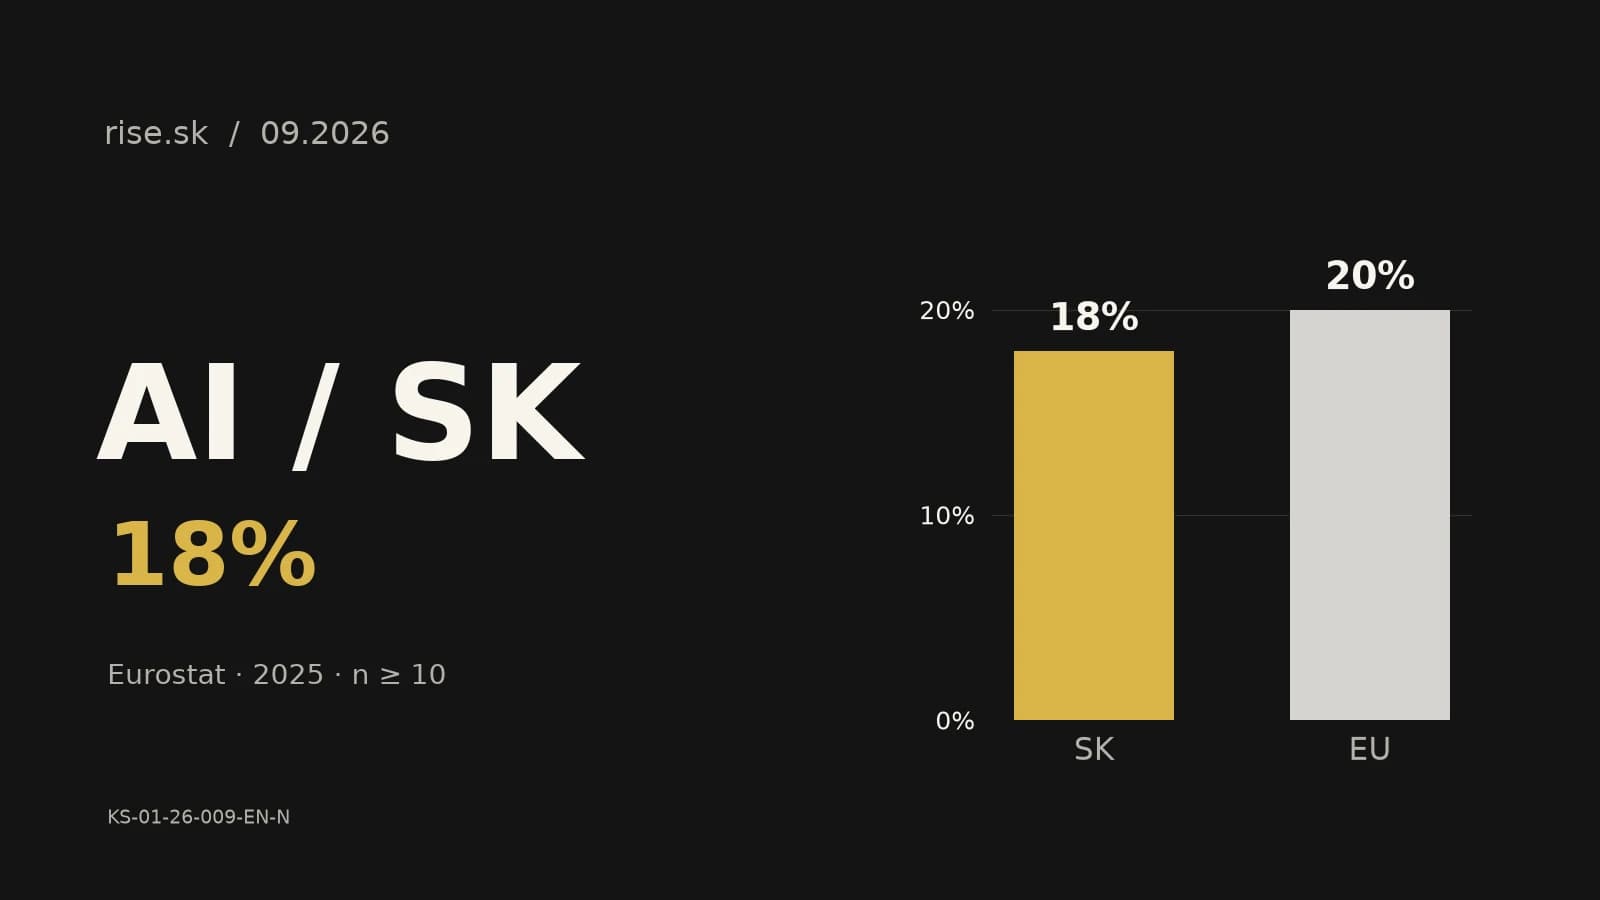
Every new AI model prompts the same question. Is it better? A company director or the head of a public office needs something more concrete than that, namely whether the same team can now finish the same work reliably, in less time, with an outcome somebody can trace afterwards.
Early September brought OpenAI's GPT-6 Astra and Anthropic's Claude Fable 5.1. Both vendors describe improvements in longer work tasks. For a Slovak organisation that is a reason to examine one specific process where the difference would show, and not grounds for replacing an information system that has been running for years.
Information is current as of 12 September 2026. The examples below are illustrative proposals. They are neither Rise implementations nor measured Rise results. Public statistics stay separate from our own arithmetic, and on product news we report what the vendor announced rather than what might actually follow from it.
OpenAI’s Astra announcement describes its intended uses. Its announcement covers computer use plus document and spreadsheet creation in multi-step tasks. The rollout began with a limited group of organisations, with broader availability planned afterwards. Check directly what a particular account has, including which tools it permits, because that varies between plans far more than anyone expects, and the gap shows up on the first real task.
The change that matters is joining steps together. A business enquiry needs more than a polite email. Someone has to compare an attachment with a catalogue, find the missing detail, put material together for the sales representative. Test that whole sequence. An overseas benchmark says nothing about whether the model will read your price list correctly or understand the Slovak abbreviation a customer typed into an order the way he always types it.
Anthropic says Fable 5.1 is generally available, while Mythos 5.1 remains under limited access. For Fable, the price of reused cached input changed. A lower price-list item does not by itself determine what a completed request costs, because that cost includes the time of the person who then reads the draft and fixes it, and nobody bills that per token.
Reusing input can help with a long document. If an employee has to correct every other answer, the model bill is the smaller half of the problem, and the larger half never appears on any invoice because it sits in that employee's hours. Compare the whole procedure including data preparation and checking. Keep the same test set when choosing a provider so one successful demonstration does not decide the outcome.
Anthropic also announced the planned Enterprise Frontier Safeguards system, with gradual availability in autumn. Do not assume it is active for every account. The distance between an announced plan and what is actually switched on in your own account is perfectly ordinary, and waiting for it is cheaper than assuming it arrived. Read the actual terms for retaining and accessing data before uploading internal documents.
A third update points the other way. Anthropic's September report on AI misuse describes selected detected cases from December 2025 to August 2026. It is not a statistic on the frequency of attacks in Slovakia, nor is it evidence that the newly released Fable 5.1 has been misused by anyone. It is a sample of what was caught, and no risk number can be computed from that.
That leads to a simple operating rule. An assistant that prepares a reply does not also need permission to send mail, change a supplier's bank account, delete attachments. Give permissions according to the task. Connecting another application is a separate decision, and before it is taken somebody has to be able to say who carries responsibility for an action the assistant performed without asking anyone.
Eurostat's Table 1 on AI use reports that 18% of Slovak enterprises used at least one tracked AI technology in 2025, against an EU average of 20%. The interesting number sits inside the country. The share was 15.6% for small Slovak enterprises and 43.7% for large ones.
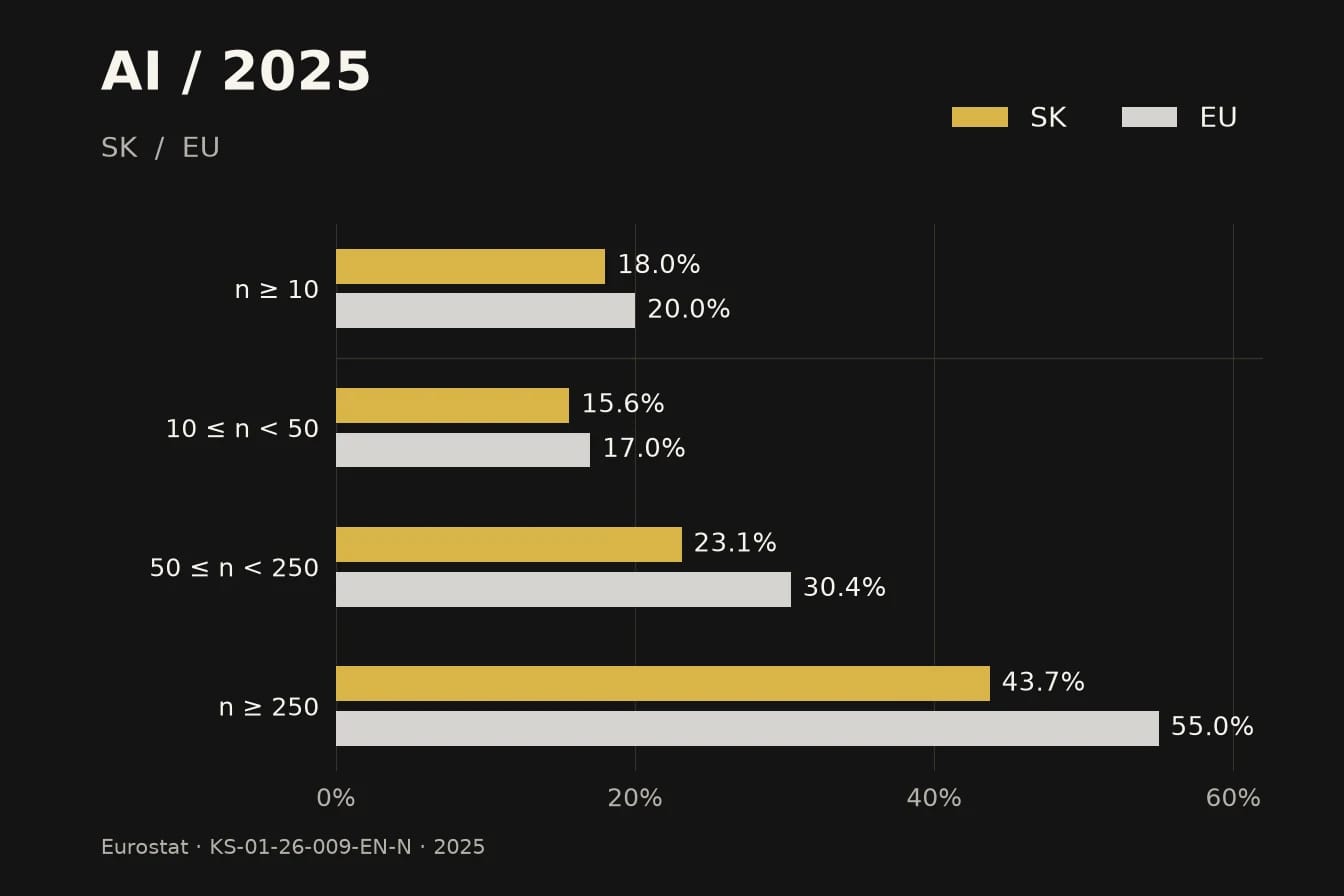
Gold represents Slovakia, grey the EU. The letter n is the number of employed persons. The gap between small and large Slovak enterprises is 28.1 percentage points.
Original chart using Eurostat data, Table 1On a smaller screen, scroll the table horizontally.
| Enterprise size by number of persons employed | Slovakia | EU |
|---|---|---|
| Total, at least 10 | 18.0% | 20.0% |
| Small, 10 to 49 | 15.6% | 17.0% |
| Medium, 50 to 249 | 23.1% | 30.4% |
| Large, 250 or more | 43.7% | 55.0% |
The figures come from a 2025 survey of selected business sectors. Public administration and enterprises with fewer than ten persons employed are excluded. The survey tracks several AI technologies, not just chatbots. It therefore cannot say how many Slovak municipalities use AI or how many companies subscribe to a particular model, those uses are outside the survey’s scope.
The gap between large and small enterprises in Slovakia is 28.1 percentage points, while only two points separate Slovakia from the EU average across all tracked enterprises. That is our subtraction of published values. Eurostat publishes no such indicator.
Both views matter for a decision. Closeness to the European average does not give smaller organisations the same opportunities as large ones. This table also cannot identify the cause of the gap or the success of any deployment, since the survey asked whether a technology is in use, not whether anything came of it. A high rate of use says nothing about return. An unsuccessful experiment still counts as AI use.
A smaller company or municipality needs an accessible starting point. It needs one understandable process, a person who already knows that process well, plus enough data to compare the old way honestly against the new one. None of that arrives with a licence.
Take a technical equipment supplier as an illustrative example. A customer emails an attachment and an incomplete product designation. The sales representative searches the catalogue and works out the parameters, then goes chasing whatever the email left out. AI could prepare a working reply draft with links to specific catalogue items, so the representative starts from something correctable rather than from an empty page.
The input must include a valid catalogue with a version date and a list of information to obtain from the customer, because without that second list the model will invent the missing fields, and it will do so convincingly. The draft should take price and stock availability from the designated system. Without them, it should mark them as unknown. An estimated delivery time in a polished email can create more work than manual handling.
The sales representative checks the match with the enquiry. Then sends it. In the first pilot, the assistant must not send the binding offer itself. Measure the time it takes to reach a sendable reply, the number of factual corrections, whether some missed detail meant contacting the customer twice for the same enquiry.
AI can make sense for reading inconsistent attachments. Moving fields already completed in a form into a CRM may need only a standard integration, with explicit rules and checks on the transferred data. We also explain the distinction in our guide on when to use an AI agent and when to use automation.
Somebody moves house. They ask how to register a waste bin. This is an illustrative situation rather than a description of any particular municipality. The assistant should find the current procedure, the relevant form, the contact for the responsible office. Its benefit shows up when the resident gets a usable answer the first time and does not have to ask the same thing again at another desk.
First put the sources in order. The municipality identifies valid documents, their effective dates, and the owner responsible for updates. An old price list in a forgotten PDF has to be distinguishable from the current regulation, or the assistant will quote a rate that expired years ago, and it will sound entirely reliable doing it. The employee needs to see the paragraph or page behind the draft. A link to the municipality website's home page is not enough.
Start with an internal assistant for an employee working with public documents. A direct resident interface comes after accuracy is verified. Where sources conflict or a question needs a personal assessment, the system should hand the case to an employee rather than attempting an answer of its own. An informational draft decides nothing. Not entitlement, not fees and nothing at all about penalties.
Track the result for the resident as well. Is the form valid? Does the link reach the correct office? Was further contact needed because the answer was incomplete? These questions say more about quality than the number of assistant conversations, a number that also goes up when people ask the same thing three times over. Keep telephone and in-person contact for people who will not use the digital service.
In an illustrative state organisation, an employee compares two versions of an internal procedure. AI could mark the changed paragraphs and list the places for the responsible subject-matter owner to assess, which is different from writing the kind of summary nobody can verify. With many documents, finding the source is worth something.
Every document needs a version number, an effective date, permissions. An employee must not obtain through the assistant information unavailable by the normal route, because the convenient tool then becomes the fastest way around every access rule at once. A citation must lead to the actual document and to the relevant place inside it. Nothing vaguer counts. If a required source is missing, it is also correct to state that the available sources cannot answer the question.
The subject-matter owner confirms the interpretation and any change to the procedure. The model never decides a person's rights. A pilot should check whether the employee finds correct, valid information faster and how many proposed differences turn out wrong, since the second number decides trust faster than the first. Deliberately test withdrawn documents and questions beyond the available sources.
For simply marking textual differences between two files, start with an ordinary document comparison, that marks textual changes according to explicit rules. Add AI where context between paragraphs or meaning-based search is needed. The route to the result must stay visible.
When selecting a provider, ask them to demonstrate on your own approved document. Check whether it flags a missing source and respects the different permissions of two employees. A polished presentation with a prepared question proves neither. Also agree who corrects the source document when the procedure changes and who checks the assistant after a model update, because the model gets updated without asking you first.
For a municipality with a small team, maintaining its own knowledge base can be harder than launching the assistant. A shared technical platform for several municipalities is possible, but each municipality's content must stay separate, or one badly drawn boundary surfaces as the wrong answer in the next village. An answer based on a neighbouring municipality's generally binding regulation is wrong even if it sounds convincing. Give equal attention to separating non-public data. A shared provider does not mean shared access permissions.
Assume 300 requests a month. The original procedure averages 12 minutes per request, and that average has to include the cases where the employee found nothing, then had to ask somebody else in person. The new one, including draft reading, source verification, corrections, averages 5 minutes. The calculation is 300 × (12 − 5) / 60 = 35 hours.
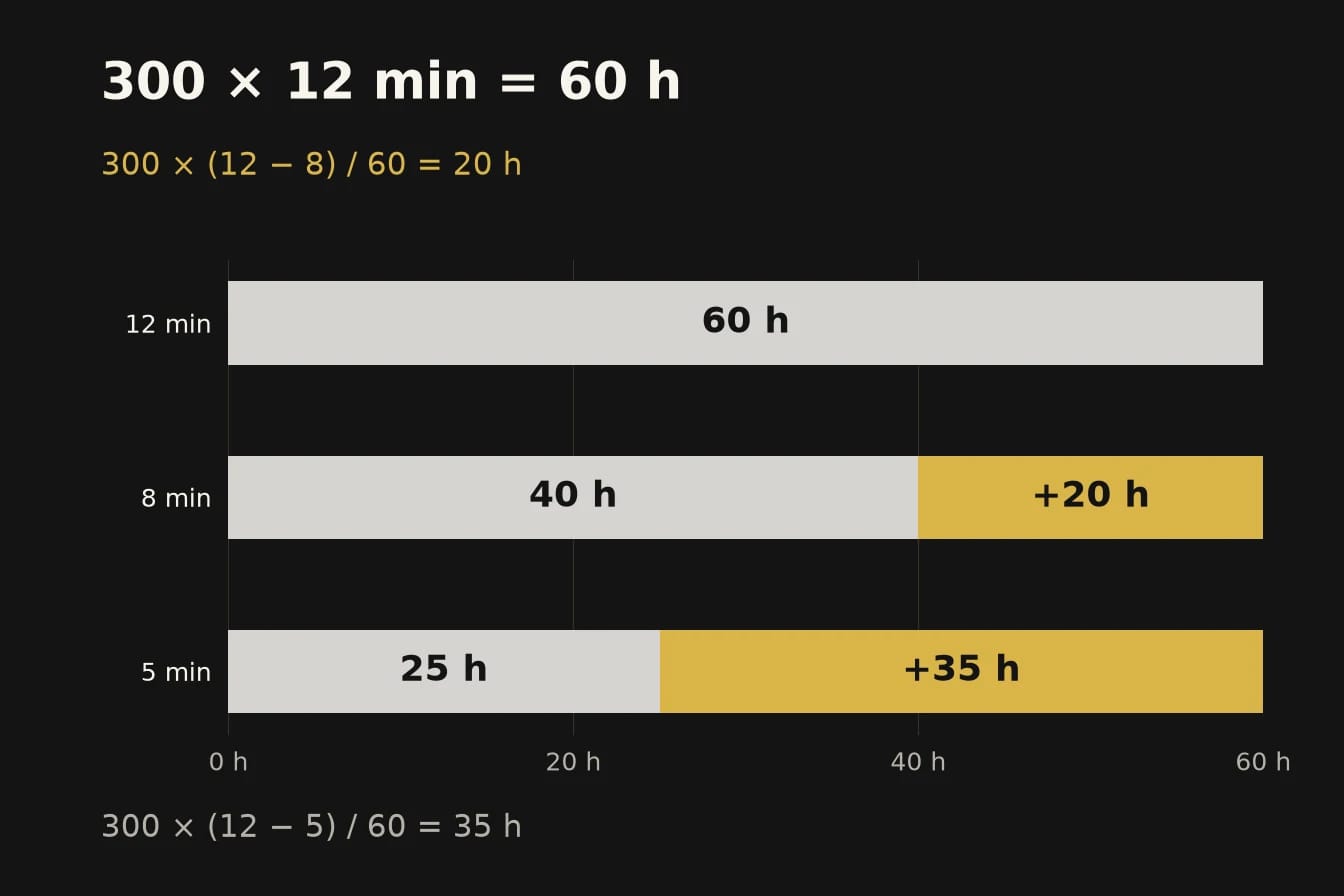
Grey shows working time, gold released capacity. This is our hypothetical calculation including review and corrections, not measured savings.
On a smaller screen, scroll the table horizontally.
| Model scenario | Average per request including review | Work for 300 requests | Capacity released |
|---|---|---|---|
| Original procedure | 12 min | 60 h | 0 h |
| New procedure, slower version | 8 min | 40 h | 20 h |
| New procedure, faster version | 5 min | 25 h | 35 h |
All table inputs are chosen assumptions. This is neither a survey nor our customer result. The averages must include the cases where AI did not help and an employee finished the work by hand, because those are the cases that decide whether the whole calculation is honest. Counting only successful drafts artificially improves the result.
Thirty-five released hours are not an automatic payroll saving. They may allow a backlog of submissions to be handled or complex cases to receive closer review. The organisation needs to know how it will use that capacity, or the 35 hours dissolve into ordinary days, and six months later nobody can say where they went. Financial evaluation also includes licences, integration, training, ongoing source maintenance.
At the same workload, every extra minute means five hours per month. Measure the review as carefully as the generation. If the new procedure averages more than the original 12 minutes, its time benefit is negative, even if the first draft arrives almost immediately, looking convincing while it does.
Choose one recurring process and its owner. For an initial test, prepare, for example, 50 historical cases you are permitted to use, and pick them so the set includes the ones nobody remembers fondly. This is a proposed test size rather than a statistical guarantee. Do not select only clean attachments and simple questions. Include missing data, old documents, cases that should end up on someone's desk.
Record the expected outcome first, then measure the original procedure. Configure the assistant with part of the cases and reserve the rest for final verification. Remember that someone who has already solved a case remembers the answer and will be faster the second time with no assistant at all, so vary the order of the cases during the test. Speed on the second attempt is no AI effect.
Before the test, define acceptable quality and the error that stops the pilot, because in practice, after the first bad result, that line moves very easily. In a municipal information service, that could be an invented fee. Or a link pointing at an invalid form. Results are evaluated by a person who knows the process. The model's self-assessment cannot replace verification.
At the end, show the time for a correctly completed request, the count of factual errors, the share of cases handed to a person, and note which of this would transfer to another process. Add the full test cost and an outage test. If the service fails, the employee must know how to continue with the original procedure. When designing access, use our checklist for connecting an AI agent to company systems.
September's models are a good reason to run this test. Expand use only afterwards. A procedure that saves a resident a repeat office visit, or removes a recurring company error, will be more valuable in Slovakia than another subscription with no clear use. When designing AI automation, start with a process you can demonstrate, measure, and hand back to people if something goes wrong.
AI supported the research, writing and translations. Public sources appear beside the claims they support. Examples and time calculations are hypothetical, not Rise customer results.

Founder and CEO of Rise.sk. He designs and delivers web applications, data systems, and automation, and writes about software decisions, AI, and digital services.
Measure the cost of a correctly completed task, including retries and human review. A verified price announcement and an illustrative calculation.

From sorting messages to checking invoices. Ten illustrative workflows and practical checks for finding out whether AI saves time after review and corrections.

GrantAI monitors grant calls, matches them to company profiles, prepares eligibility analysis, and drafts application materials. Demo and pilot for grant teams.